Data Engineering with AI
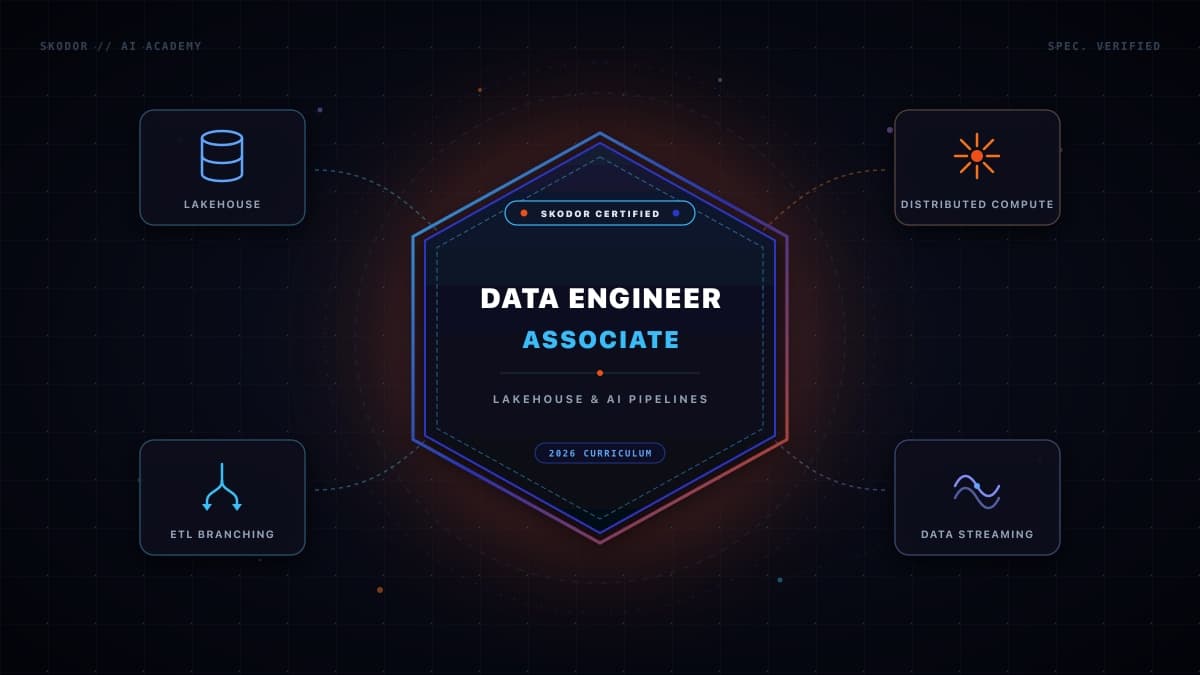
Master scalable data pipelines, distributed big data architectures, cloud lakehouses, and AI-powered data workflows.
4–6 Months
3 Months Practical
Verified Projects
5 Core Modules
Engineered for High Technical Competence
Data Engineering with AI is engineered for learners who want to build high-performance data infrastructure powering modern analytical engines and artificial intelligence. You will learn the end-to-end data lifecycle—from ingestion, batch and real-time streaming, lakehouse storage, and data transformations to preparing enterprise data specifically for LLMs and AI agents.
What You Will Master
- Design robust, fault-tolerant ETL and ELT data pipelines using Python, SQL, and dbt
- Process large-scale datasets with Apache Spark, PySpark, and Delta Lake Medallion Architecture
- Orchestrate complex dependent workflows using Apache Airflow DAGs
- Stream high-velocity events in real-time with Apache Kafka and Spark Streaming
- Construct modern Lakehouse architectures on Snowflake, BigQuery, and major cloud platforms
- Develop specialized vector data pipelines and unstructured data chunking systems for Generative AI and RAG
Detailed Course Syllabus
All topics and modules are extracted directly from the official course specification.
5 Detailed Syllabus Modules
Tools & Technologies Taught
Directly aligned with production engineering environments.
Capstone Projects
Two comprehensive capstone projects demonstrating end-to-end cloud platform engineering and automated AI pipeline architectures.
End-to-End Cloud Data Platform
Sprint ProjectDesign and deploy a scalable data lakehouse processing multi-source batch and streaming data with Apache Spark, Airflow, and dbt.
AI-Powered RAG Data Pipeline
Sprint ProjectBuild an ingestion and indexing pipeline converting unstructured enterprise documents into vectorized embeddings for retrieval-augmented generation.
3-Month Practical Internship
Hands-on internship building and maintaining production data pipelines with real enterprise schemas and streaming workloads.
Internship Highlights
- Structured engineering sprint cadence
- Peer code reviews and architecture defense
- Portfolio deployment to production cloud instances
Verified Course Learning Outcomes
Course Specific Questions
What prior knowledge is required for this program?
Basic programming concepts and fundamental familiarity with mathematics are helpful. The course starts from core programming and SQL foundations before advancing to distributed systems.
Does the program include practical hands-on projects?
Yes. Every module features hands-on lab exercises, culminating in two full-scale capstone projects (a Cloud Data Platform and an AI-Powered RAG Data Pipeline).
How is the 3-month internship structured?
Following the core coursework, learners transition into a 3-month internship where they work on real-world engineering problem statements, pipeline optimizations, and architectural challenges.
Earn Your Data Engineering with AI Certification
Every successful graduate receives an industry-recognized certificate demonstrating verifiable competence in real-world systems, architectures, and practical engineering execution.
Proof of Practical Engineering Autonomy
Unlike traditional course certificates awarded for passive video watching, SKODOR credentials prove that you built, debugged, and shipped commercial-grade systems.
Verifiable Credential
Includes unique cryptographic credential ID and instant QR code verification for recruiters and hiring managers.
Demonstrated Production Skills
Issued only upon completing all technical modules, code reviews, and defending live capstone deliverables.
Shareable Globally
Seamlessly add your verified SKODOR certificate to LinkedIn, personal engineering portfolios, and resumes.
Verified with immutable credential ID • Globally shareable on LinkedIn
Enroll in Data Engineering with AI
Cohorts have limited seating to maintain high mentor-to-student interaction and rigorous code reviews. Speak with an admissions advisor today.